🥳 Our paper has been accepted for an oral presentation at AAAI-26!
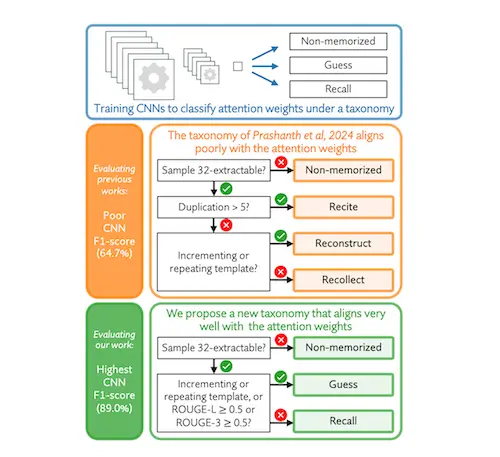
🧠 What is it about? We address an important gap in the literature on pre-training data memorization in LLMs. We show that verbatim memorization is a multifaceted phenomenon and propose a mechanistic approach to distinguish between several types of memorization. By localizing the regions of LLMs responsible for each mechanism, we demonstrate the benefits of separating these different forms of memorization.
🐿️ Our approach in a nutshell As often in mechanistic interpretability, we train small models to better understand the computational artifacts of larger models. Specifically, we train CNNs to classify attention weights measured during LLM verbatim memorization. This allows us to access the causal mechanisms underlying memorization and classify them in a taxonomy. Finally, we developed a custom interpretability technique for CNNs to identify the regions of the attention weights responsible for memorization.
🤝 This work was done in collaboration with Davide Buscaldi and Sonia Vanier, as part of the "Responsible and Trustworthy AI" research chair between École Polytechnique and Groupe Crédit Agricole. This acceptance highlights the scientific importance of privacy and security in AI, supported by this fruitful partnership.
See you in Singapore in January 😃🇸🇬